April 2026, open source
CU Benchmark Suite
Python, PyTorch, CUDA/ROCm, NCCL, Docker, GitHub Actions
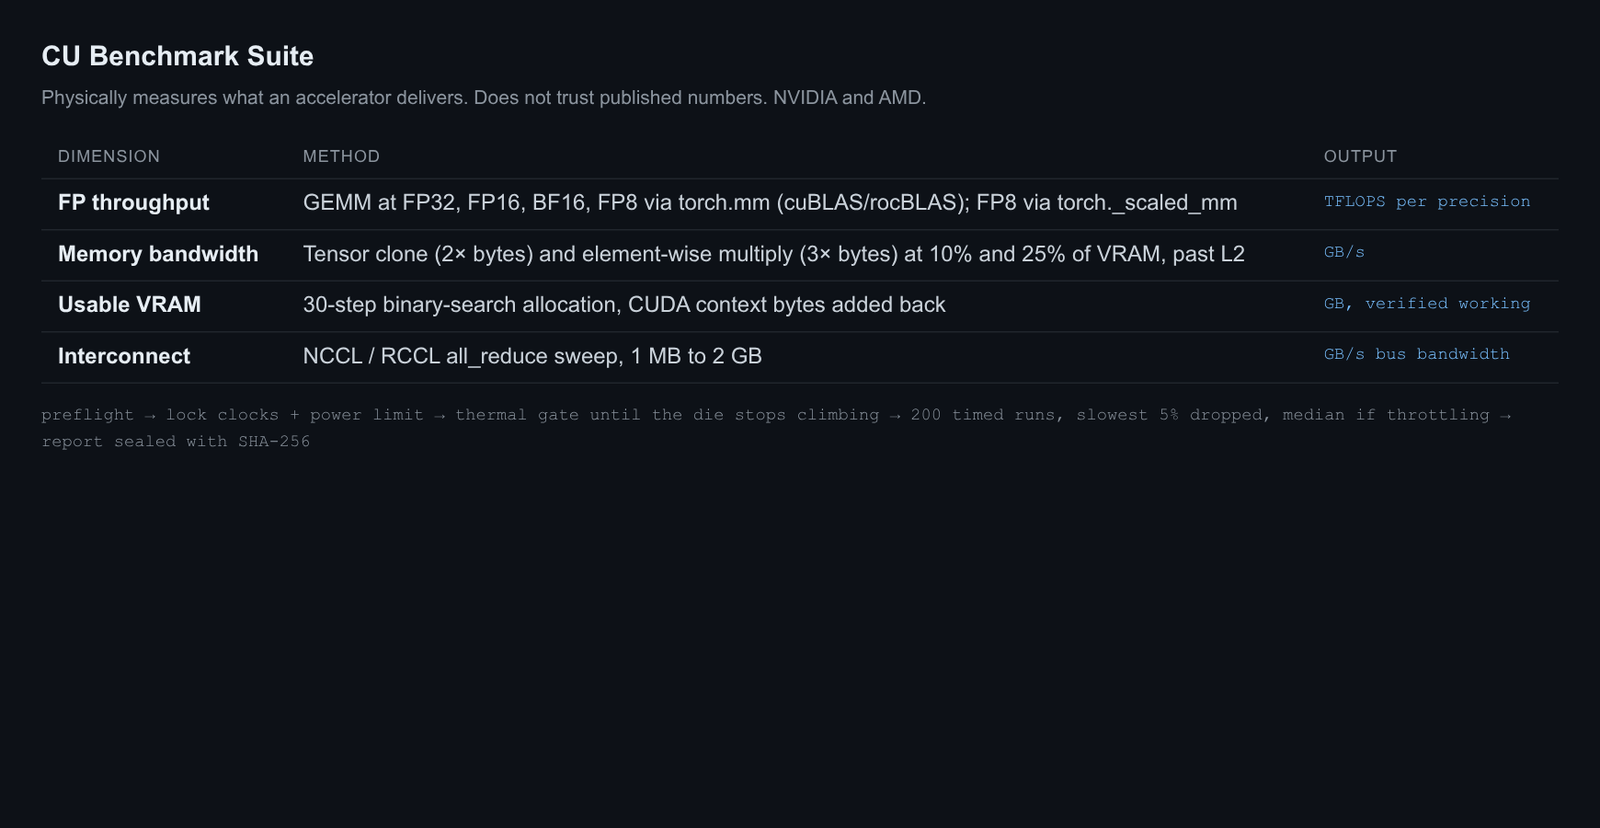
Measures exactly what an accelerator delivers at the hardware level, with PyTorch on CUDA and ROCm: FP throughput via GEMM at FP32/FP16/BF16/FP8, memory bandwidth via tensor copy, usable VRAM by binary-search allocation, and interconnect via NVIDIA's nccl-tests and AMD's rccl-tests with all_reduce_perf. NVIDIA and AMD.
Before measuring, the suite pins the GPU clocks and power limit to the manufacturer's rated values, then runs sustained GEMM until the die temperature stops climbing. A cold card boosts above its sustained speed, so without this step two cards get compared at two different operating points.